iceBook Vertex MX10
Ultra-Small AI Supercomputer
iceBook Vertex MX10
Based on AMD Ryzen™ AI MAX+ 395 Processor
The iceBook Vertex MX10, accelerated by the powerhouse AMD Ryzen™ AI Max+ 395 processor and full-stack AI software, packs workstation-grade AI compute into your desktop. Its ultra-compact Mini PC footprint facilitates seamless local LLM deployment, delivering class-leading AI TOPS for innovators who demand excellence without cloud dependency.
AMD Ryzen™ AI MAX 395
Flagship Strix Halo architecture
(16 cores / 32 threads)
AMD Radeon™ 8060S
Revolutionary graphics for gaming, 3D, and rendering
NPU AMD Ryzen™ AI
Hardware acceleration for local AI
Over 50 TOPS
132–175W TDP
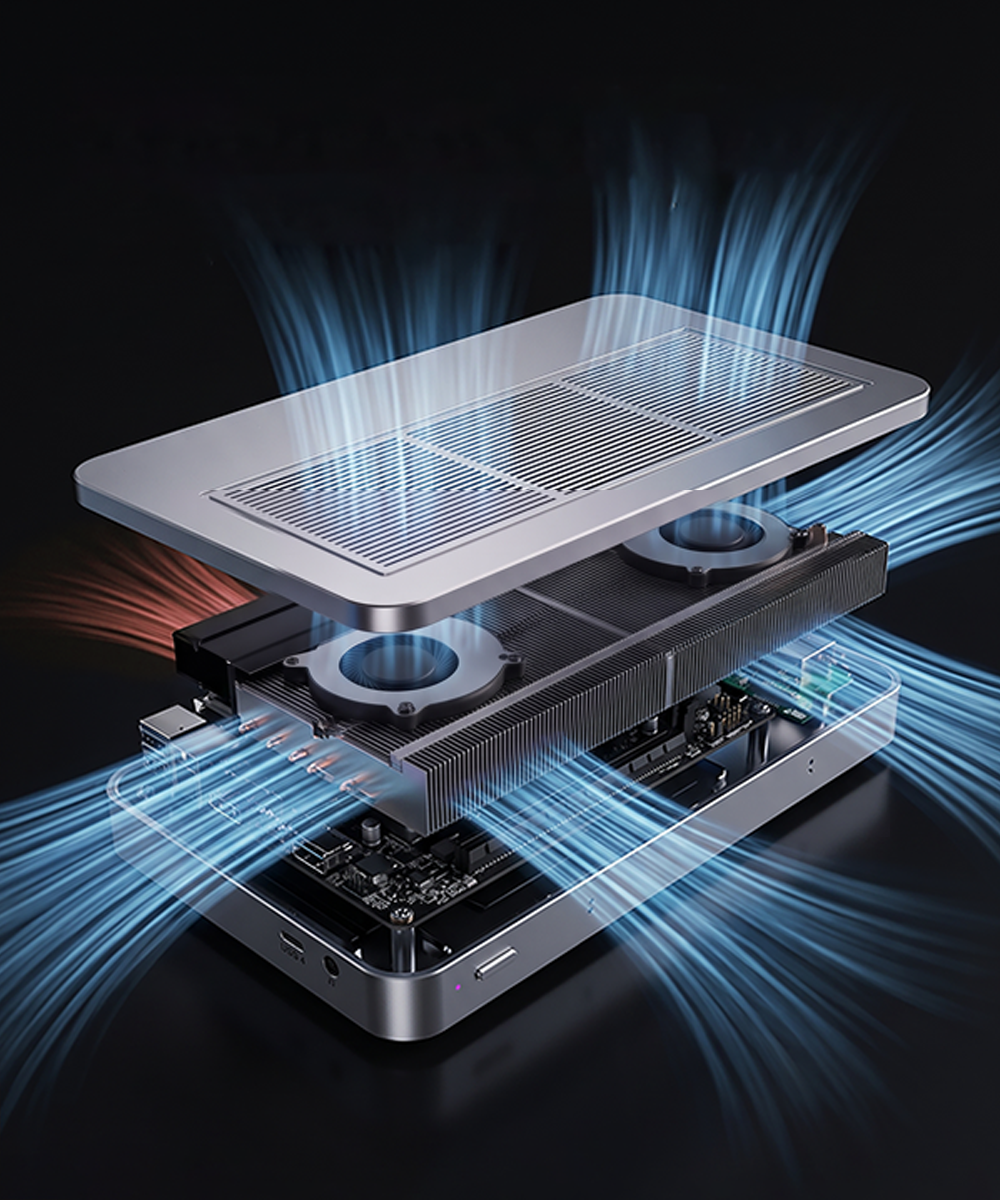
Optimized Cooling Design, stable operation
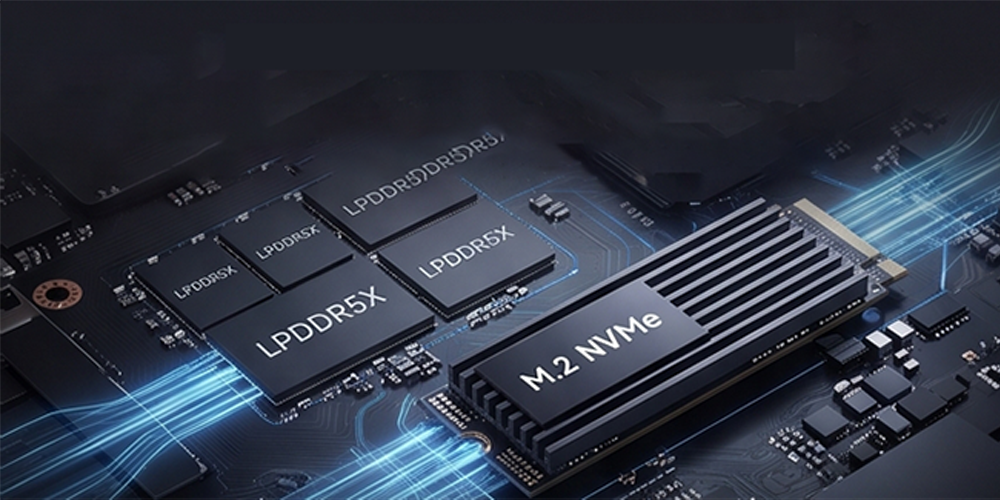
128 GB LPDDR5X 7500 MT/s
1 TB M.2 2280 NVMe SSD
Wi-Fi 7 (802.11be)
Ultra-low latency and MLO multi-link operation
Windows 11
Ubuntu Linux
Perfect for Dual OS
Bluetooth 5.4
Stable connection and minimal latency
Empowering the Best Minds
Engineered with the 16-core, 32-thread AMD Ryzen™ AI MAX+ 395 processor, our server provides local, queue-free AI acceleration across critical workloads.
AI Researchers
AI Educators
AI Developers
Revolutionary AI Performance on Your Desktop
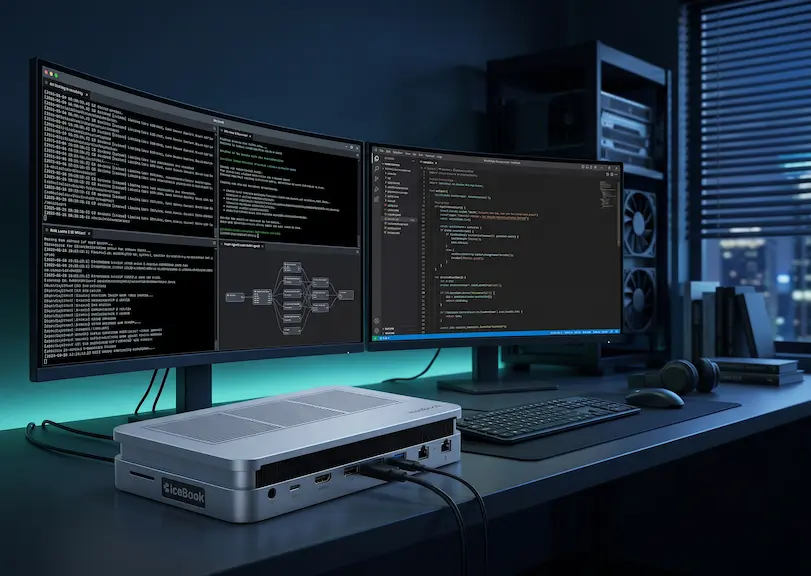
The groundbreaking iceBook Vertex MX10 brings workstation-class AI computing capabilities directly to the desks of developers, AI researchers, and data scientists. Empower local AI development with extreme thermal efficiency and whisper-quiet operation.
Compact, Powerful, and Scalable
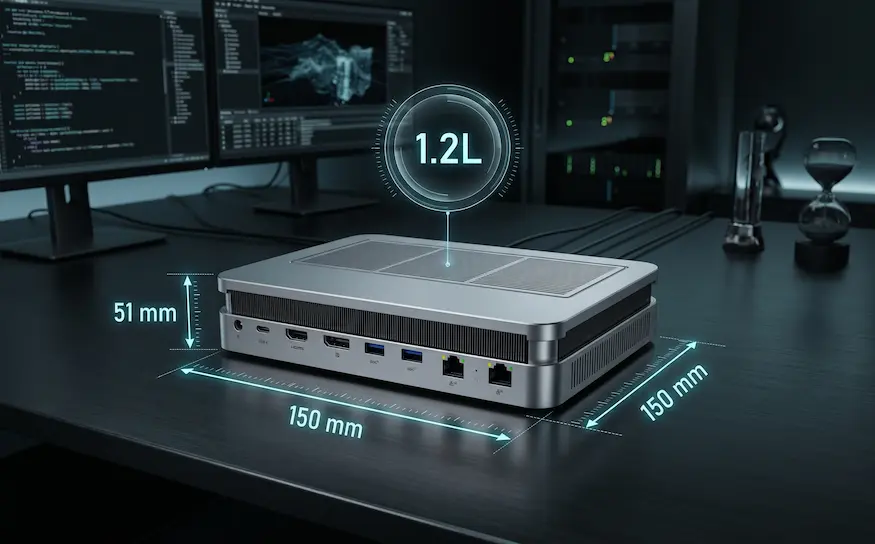
Ultra-dense 1.2L chassis: 150 x 150 x 51 mm
Unparalleled AI Performance
Cutting-Edge Architecture
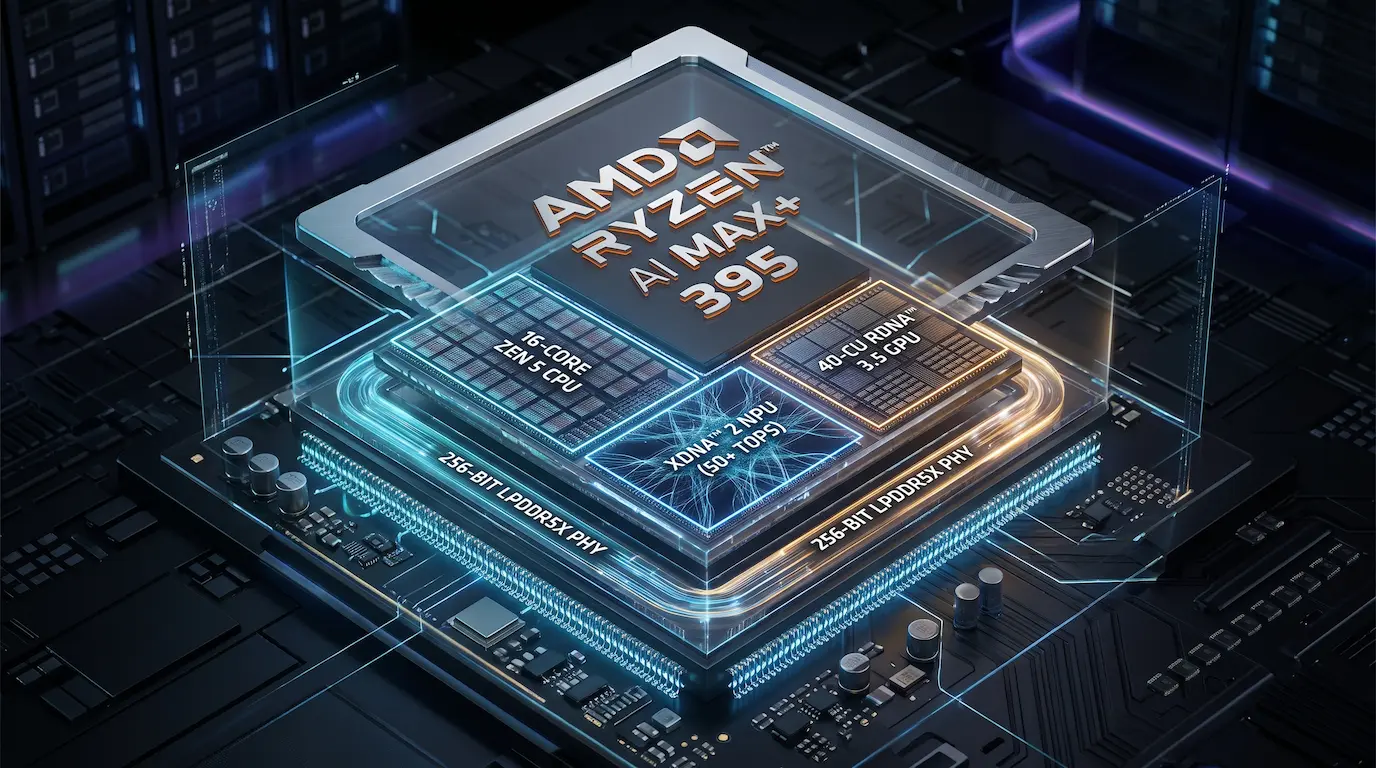
AMD Ryzen™ AI MAX+ 395 Processor
Central to the MX10, this flagship "Strix Halo" APU integrates massive compute engines to execute agentic workflows flawlessly.
16-Core / 32-Thread Zen 5 CPU
Provides top-tier single and multi-threaded throughput, accelerating data preprocessing, compilation, and orchestration.
AMD XDNA™ 2 NPU & RDNA™ 3.5 GPU
Features dedicated NPU acceleration (50+ TOPS) alongside a robust 40-CU graphics engine for uncompromising local AI modeling.
Deploy Frontier Local LLMs
Support for 100B+ Parameter Models
Leverage 128GB of LPDDR5x unified memory to prototype, fine-tune, and run flagship models like Llama 3 70B or Mixtral locally with zero quantization bottleneck.
High-Speed AI Node Clustering
Link multiple iceBook Vertex MX10 systems via ultra-fast USB4 and Multi-Gigabit Ethernet to scale your multi-agent workflows effortlessly.
Meets Next-Gen I/O: Ultra-Fast Bandwidth
Equipped with cutting-edge connectivity to deliver rapid data transfer and low-latency communication across your local network and distributed AI workloads.
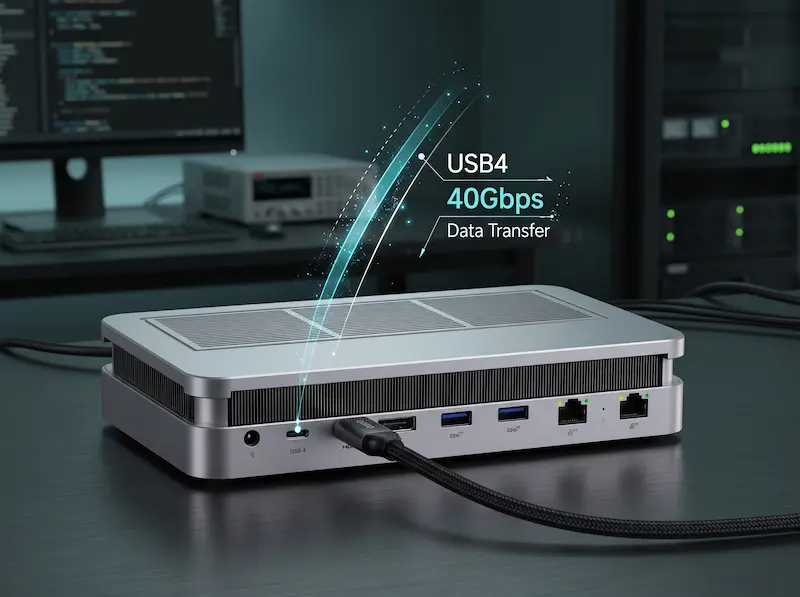
Dual USB4 40Gbps
Unleash extreme bandwidth. Connect external AI accelerators, ultra-fast NVMe storage arrays, or dual 8K displays with lightning-fast 40Gbps throughput.
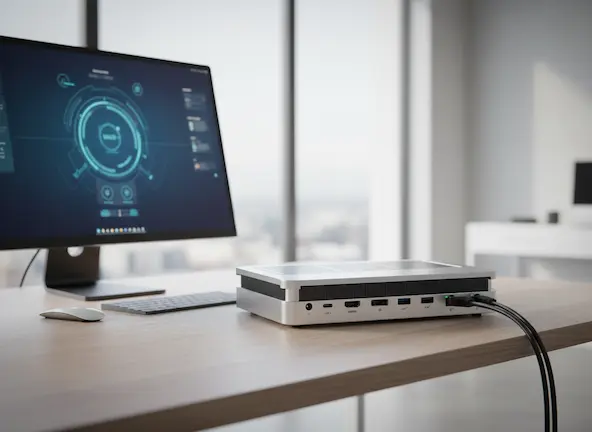
Multi-Gigabit LAN
Low-latency dual RJ45 ports ensure rock-solid wired connectivity, perfect for continuous dataset fetching, NAS integration, or orchestrating local AI clusters.
Next-Gen Wireless
Built-in advanced Wi-Fi and Bluetooth capabilities allow for seamless edge deployments, OTA updates, and wireless integration with IoT sensor networks.
Preloaded AI for Instant Development
Ubuntu-based DGX OS environment comes pre-configured with drivers, CUDA, and container runtimes out of the box.
Optimized AI Tools & Frameworks
Native support for PyTorch, vLLM, TensorRT-LLM, Ollama, and NVIDIA NIM microservices for one-click deployment.
Scale from Desk to Cloud
Develop locally on MX10 and seamlessly migrate containers to enterprise DGX cloud or on-prem server clusters.
Power Agentic AI Locally Without Perpetual Token Costs
Run autonomous AI agents (OpenClaw, LangGraph, AutoGen) 24/7 with zero API fees and complete on-premises data sovereignty.
$ icebook-agent start --model deepseek-r1-70b --quant fp4
[INFO] Loading 128GB Unified Memory Pool...
[READY] Local Inference Engine active at 48.5 tokens/sec
[AGENT] Autonomous workflow connected: Email, Calendar, Codebase
_ Waiting for local task execution (0 Cloud Token Cost)
Enterprise-Grade Stability & Privacy
Featuring 1 PetaFLOP of AI performance and 128GB of memory, MX10 empowers you to run complex multi-agent frameworks on-demand. Keep sensitive codebases, financial records, and proprietary weights strictly inside your firewall.
- ● 24/7 Continuous AI Execution
- ● Zero Third-Party API Dependency
- ● 100% On-Premises Data Sovereignty
Precision-Crafted for Ultimate Thermal Efficiency
Tackle AI's most demanding workloads with the iceBook Vertex MX10. Its advanced dual-blower vapor chamber design with 7-level smart control delivers smooth, precise airflow. With 1.6x more efficient thermal coverage than comparable compact systems, MX10 stays cool and consistently performs at its peak.
Sustained Performance Under Heavy Cluster Workloads
Engineered with side-intake and rear-exhaust channels, multiple MX10 units can be vertically stacked or rack-mounted without thermal throttling, forming a formidable desktop AI cluster.
Pro-Grade I/O Ports
Local Development, Scalable Deployment
Prototyping
Rapidly iterate on RAG pipelines and agentic prompts using local Jupyter notebooks and Ollama.
Fine-Tuning / Inference
Keep proprietary datasets in-house while performing LoRA fine-tuning on 70B+ foundation models.
Data Science
Accelerate dataframe processing and graph analytics with the unified 128GB CPU-GPU memory pool.
iceBook Virtual Lab
To help you evaluate your needs before investing, iceBook has set up a Virtual Lab program. This is a remote, on-demand environment with access to a single or dual Vertex MX10 for up to 72 hours. Validate performance and test your actual AI workloads risk-free.
Stay Informed About Future Innovations!
Sign up to be the first to know about upcoming iceBook AI supercomputing products and enterprise cluster solutions.
*Specifications and product images are subject to change.